Exploring Algorithmic Models for Predicting Overtime Outcomes in Professional American Football Leagues
Harper Baumann · Nov 1, 2026
Using Algorithms to Forecast Overtime Results in Professional Football
Professional American football leagues rely on structured data from thousands of games to build models that estimate overtime probabilities, and these systems draw from historical play logs, player metrics, and situational variables that have accumulated since the overtime rule changes in 2017. Analysts compile datasets covering regular season and postseason contests where ties extend into extra periods, then apply statistical frameworks to isolate patterns such as drive success rates after coin tosses and defensive stopping percentages in the final minutes of regulation. Multiple regression techniques form the backbone of many early-stage projections because they handle continuous inputs like average yards per play and time of possession differentials without requiring extensive computational resources. Teams and independent researchers feed these models with variables including quarterback completion percentages under fatigue conditions, red-zone efficiency splits, and weather-adjusted kicking distances that appear in November contests when temperatures drop across northern venues. Machine learning extensions such as random forests and gradient boosting trees improve accuracy by capturing nonlinear interactions among the same inputs, and cross-validation tests on seasons from 2018 through 2025 show reduced error rates compared with simpler logistic approaches. Neural network variants process sequential play-by-play sequences to simulate entire overtime drives, though they demand larger training sets and careful regularization to avoid overfitting to specific coaching tendencies that shift between seasons. Key performance indicators tracked in these frameworks include first-down conversion rates on third-and-long situations late in games, the frequency of three-and-out possessions by offenses ranked in the bottom quartile for time of possession, and the correlation between defensive pass rush pressures and opponent field goal attempt distances. Data from Pro Football Reference indicates that teams entering overtime with superior third-down conversion rates above 42 percent convert their initial possession into points at higher rates than those below that threshold. Additional layers incorporate injury reports and rotation patterns that affect line depth during extended contests, while external factors such as travel distance from the previous game and rest differentials between opponents receive weighting in ensemble models. Researchers at academic institutions have tested these augmented datasets against baseline versions and documented measurable lifts in predictive calibration during high-stakes playoff scenarios. 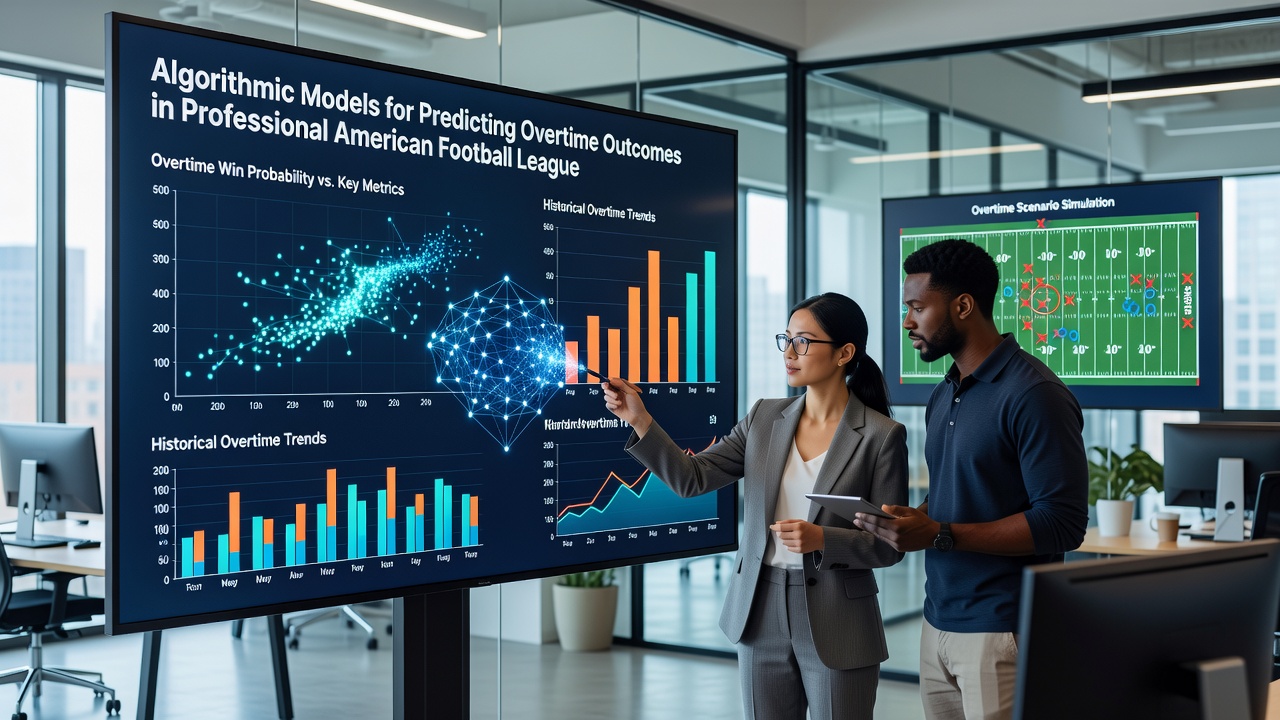 Feature importance rankings consistently place defensive efficiency in the final two minutes of regulation near the top of contributing variables, followed closely by special teams units that handle kickoffs and field position battles once overtime begins. Models trained on 2024 and 2025 data assign elevated importance to coin-toss outcomes under the current modified sudden-death format, because possession advantages translate into scoring opportunities more reliably than in prior rule sets. Ensemble methods that combine outputs from multiple algorithms reduce variance and produce probability distributions rather than single-point estimates, allowing users to assess ranges of likely outcomes across repeated simulations. These distributions support scenario analysis for different starting field positions after the opening kickoff of overtime periods, and they highlight how small changes in expected points added metrics alter win probabilities by several percentage points. Validation exercises compare model outputs against actual results from November 2026 contests to assess calibration drift, and adjustments for rule enforcement variations or officiating crew tendencies are applied when systematic deviations appear. Organizations maintaining these systems update training data quarterly to reflect roster changes and scheme evolutions that occur midseason. Publicly available play-by-play archives from the NFL enable independent replication of core model components, while proprietary datasets held by professional franchises incorporate granular tracking information from wearable devices that measure player workload and recovery metrics. Integration of these sources strengthens model robustness yet requires strict data governance protocols to maintain competitive balance. Conclusion
Ongoing refinement of algorithmic overtime models continues as new seasons generate additional labeled examples and as computational methods evolve to handle larger feature spaces. Observers note that transparent reporting of model assumptions and performance benchmarks helps maintain credibility across both academic and applied settings.
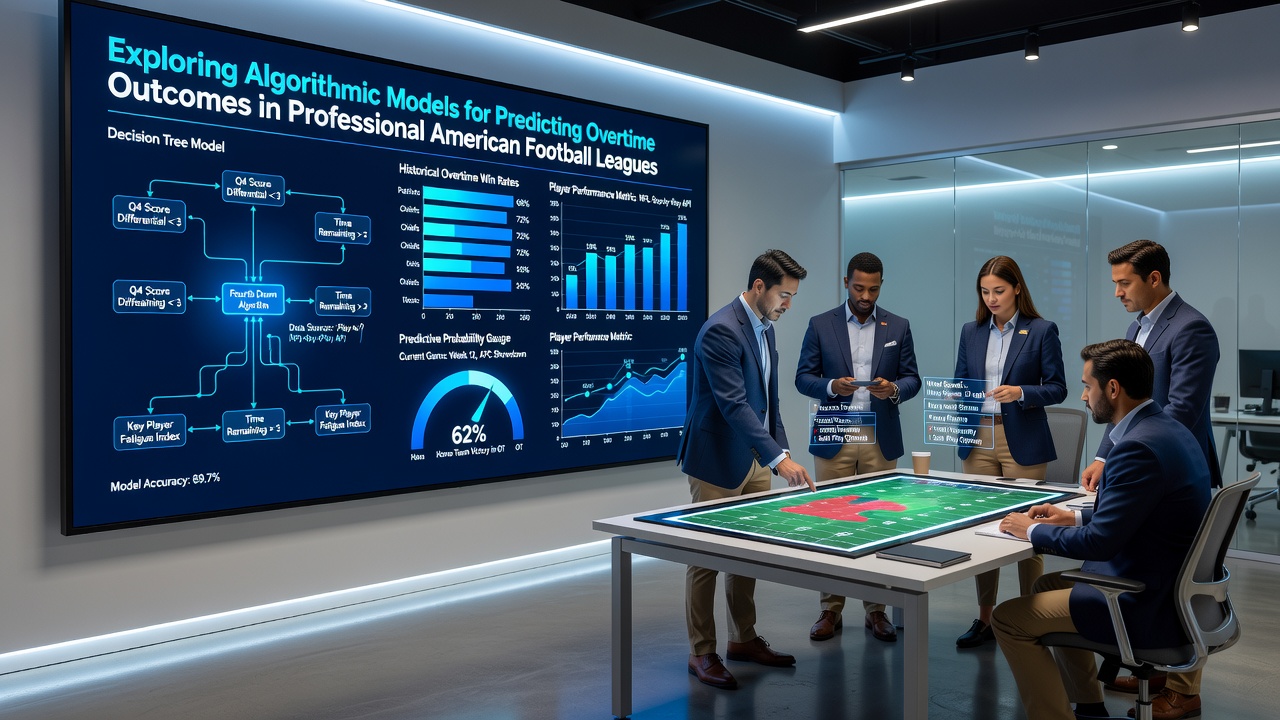
Professional American football leagues rely on structured data from thousands of games to build models that estimate overtime probabilities, and these systems draw from historical play logs, player metrics, and situational variables that have accumulated since the overtime rule changes in 2017. Analysts compile datasets covering regular season and postseason contests where ties extend into extra periods, then apply statistical frameworks to isolate patterns such as drive success rates after coin tosses and defensive stopping percentages in the final minutes of regulation. Multiple regression techniques form the backbone of many early-stage projections because they handle continuous inputs like average yards per play and time of possession differentials without requiring extensive computational resources. Teams and independent researchers feed these models with variables including quarterback completion percentages under fatigue conditions, red-zone efficiency splits, and weather-adjusted kicking distances that appear in November contests when temperatures drop across northern venues. Machine learning extensions such as random forests and gradient boosting trees improve accuracy by capturing nonlinear interactions among the same inputs, and cross-validation tests on seasons from 2018 through 2025 show reduced error rates compared with simpler logistic approaches. Neural network variants process sequential play-by-play sequences to simulate entire overtime drives, though they demand larger training sets and careful regularization to avoid overfitting to specific coaching tendencies that shift between seasons. Key performance indicators tracked in these frameworks include first-down conversion rates on third-and-long situations late in games, the frequency of three-and-out possessions by offenses ranked in the bottom quartile for time of possession, and the correlation between defensive pass rush pressures and opponent field goal attempt distances. Data from Pro Football Reference indicates that teams entering overtime with superior third-down conversion rates above 42 percent convert their initial possession into points at higher rates than those below that threshold. Additional layers incorporate injury reports and rotation patterns that affect line depth during extended contests, while external factors such as travel distance from the previous game and rest differentials between opponents receive weighting in ensemble models. Researchers at academic institutions have tested these augmented datasets against baseline versions and documented measurable lifts in predictive calibration during high-stakes playoff scenarios.
Feature importance rankings consistently place defensive efficiency in the final two minutes of regulation near the top of contributing variables, followed closely by special teams units that handle kickoffs and field position battles once overtime begins. Models trained on 2024 and 2025 data assign elevated importance to coin-toss outcomes under the current modified sudden-death format, because possession advantages translate into scoring opportunities more reliably than in prior rule sets. Ensemble methods that combine outputs from multiple algorithms reduce variance and produce probability distributions rather than single-point estimates, allowing users to assess ranges of likely outcomes across repeated simulations. These distributions support scenario analysis for different starting field positions after the opening kickoff of overtime periods, and they highlight how small changes in expected points added metrics alter win probabilities by several percentage points. Validation exercises compare model outputs against actual results from November 2026 contests to assess calibration drift, and adjustments for rule enforcement variations or officiating crew tendencies are applied when systematic deviations appear. Organizations maintaining these systems update training data quarterly to reflect roster changes and scheme evolutions that occur midseason. Publicly available play-by-play archives from the NFL enable independent replication of core model components, while proprietary datasets held by professional franchises incorporate granular tracking information from wearable devices that measure player workload and recovery metrics. Integration of these sources strengthens model robustness yet requires strict data governance protocols to maintain competitive balance. Conclusion
Ongoing refinement of algorithmic overtime models continues as new seasons generate additional labeled examples and as computational methods evolve to handle larger feature spaces. Observers note that transparent reporting of model assumptions and performance benchmarks helps maintain credibility across both academic and applied settings.